

- If you have a fleet of vehicles where events represent departure and return, you may wish to ask during what periods are at least one of my vehicles out and when are they all not being used?
- In a manufacturing plant with multiple assembly lines where events are line starts and line stops, you can find out during what periods at least one line is in use or the periods when all lines are idle.
- By adding a bit of PARTITIONing to these queries, you can handle the case of a hotel that has multiple types of rooms. Then you can ask the questions, during what times is at least one room of a type occupied or when are all rooms of a particular type unoccupied.
Problem Setup and Explanation
First we’ll create a table with some basic set-up data that represents three user logins. The login periods will overlap and contain a gap to illustrate the essentials of what we are trying to do.|
1 2 3 4 5 6 7 8 9 10 11 12 13 14 15 16 17 18 19 20 21 22 |
IF OBJECT_ID('tempdb.dbo.#Events', 'U') IS NOT NULL DROP TABLE #Events; CREATE TABLE #Events ( ID BIGINT IDENTITY PRIMARY KEY ,UserID INT ,EventTime DATETIME ,[Event] TINYINT -- 0=Login, 1=Logout ); INSERT INTO #Events SELECT 1, '2013-09-01 15:33', 0 UNION ALL SELECT 2, '2013-09-01 16:15', 0 UNION ALL SELECT 2, '2013-09-01 17:00', 1 UNION ALL SELECT 3, '2013-09-01 17:10', 0 UNION ALL SELECT 1, '2013-09-01 18:20', 1 UNION ALL SELECT 3, '2013-09-01 19:10', 1 UNION ALL SELECT 1, '2013-09-02 11:05', 0 UNION ALL SELECT 1, '2013-09-02 11:45', 1; SELECT * FROM #Events ORDER BY UserID, EventTime; |
|
1 2 3 4 5 6 7 8 9 |
ID UserID EventTime Event 1 1 2013-09-01 15:33:00.000 0 5 1 2013-09-01 18:20:00.000 1 7 1 2013-09-02 11:05:00.000 0 8 1 2013-09-02 11:45:00.000 1 2 2 2013-09-01 16:15:00.000 0 3 2 2013-09-01 17:00:00.000 1 4 3 2013-09-01 17:10:00.000 0 6 3 2013-09-01 19:10:00.000 1 |
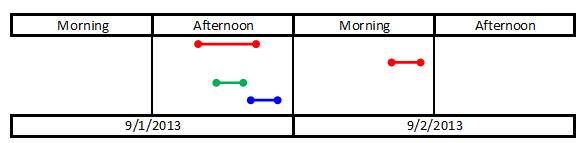 Each login ID is represented by a different color. You can see that there are overlaps between the grouping of logins on the afternoon of 01 Sep and the single login by UserID=1 on 02 Sep. From the data, we ultimately seek to expose the gap between the logout of UserID=3 (blue) and the second login of UserID=1 (2013-09-01 19:10 to 2013-09-02 11:05).
Pairing of Different, Sequential Events
The following solutions assume that concurrent logins by a single account are not allowed. When your login/logout events are equally paired, i.e., there are no missing logout endpoints, a solution such as I’ll be describing will group these events so that your query can place start/end times of the events on a single row.Sample Query #1: How to Pair up Logins with Logouts
|
1 2 3 4 5 6 7 8 9 10 11 |
SELECT UserID, LoginTime=MIN(EventTime), LogoutTime=MAX(EventTime) FROM ( -- Construct a row number (rn) that is 1, 1, 2, 2, 3, 3, ... for each row SELECT UserID, EventTime ,rn=(ROW_NUMBER() OVER (PARTITION BY UserID ORDER BY EventTime)-1)/2 FROM #Events ) a -- When we group by rn we have paired sessions GROUP BY UserID, rn ORDER BY UserID, LoginTime; |
Results from Sample Query #1:
|
1 2 3 4 5 |
UserID LoginTime LogoutTime 1 2013-09-01 15:33:00.000 2013-09-01 18:20:00.000 1 2013-09-02 11:05:00.000 2013-09-02 11:45:00.000 2 2013-09-01 16:15:00.000 2013-09-01 17:00:00.000 3 2013-09-01 17:10:00.000 2013-09-01 19:10:00.000 |
Note how, in the derived table, we’ve created a grouping column as (ROW_NUMBER()+1)/2, which is a well-known trick for pairing consecutive rows. Here are the results in rn for the first four rows:
|
1 2 3 4 5 |
1. (1+1)/2 = 1 2. (2+1)/2 = 1 (integer division truncates the result) 3. (3+1)/2 = 2 4. (4+1)/2 = 2 (integer division truncates the result) 5. ... |
|
1 2 3 4 5 |
INSERT INTO #Events SELECT 1, '2013-09-01 18:00', 0 UNION ALL SELECT 2, '2013-09-01 18:01', 0; SELECT * FROM #Events ORDER BY UserID, EventTime; |
|
1 2 3 4 5 6 7 8 9 10 11 |
ID UserID EventTime Event 1 1 2013-09-01 15:33:00.000 0 9 1 2013-09-01 18:00:00.000 0 5 1 2013-09-01 18:20:00.000 1 7 1 2013-09-02 11:05:00.000 0 8 1 2013-09-02 11:45:00.000 1 2 2 2013-09-01 16:15:00.000 0 3 2 2013-09-01 17:00:00.000 1 10 2 2013-09-01 18:01:00.000 0 4 3 2013-09-01 17:10:00.000 0 6 3 2013-09-01 19:10:00.000 1 |
Sample Query #2: Pairing Logins with no Corresponding Logout
|
1 2 3 4 5 6 7 8 9 10 11 12 13 14 15 16 |
SELECT UserID, LoginTime=a.EventTime, LogoutTime=b.EventTime FROM #Events a -- Use an OUTER APPLY to retain outer query rows when inner query returns NULL OUTER APPLY ( -- find the first of any events for this user after the login. If a logout -- then use its EventTime. If a login return NULL -- For logout events (Event=1) pick up the EventTime as the time of logout SELECT TOP 1 EventTime=CASE WHEN [Event] = 1 THEN EventTime END FROM #Events b WHERE a.UserID = b.UserID AND b.EventTime > a.EventTime ORDER BY b.EventTime ) b -- Filter on only login events WHERE [Event] = 0 ORDER BY UserID, LoginTime; |
Results from Sample Query #2:
|
1 2 3 4 5 6 7 |
UserID LoginTime LogoutTime 1 2013-09-01 15:33:00.000 NULL 1 2013-09-01 18:00:00.000 2013-09-01 18:20:00.000 1 2013-09-02 11:05:00.000 2013-09-02 11:45:00.000 2 2013-09-01 16:15:00.000 2013-09-01 17:00:00.000 2 2013-09-01 18:01:00.000 NULL 3 2013-09-01 17:10:00.000 2013-09-01 19:10:00.000 |
Sample Query #3: Using LEAD to Improve Performance (where some logins have no logout)
|
1 2 3 4 5 6 7 8 9 10 11 12 13 14 15 16 17 18 |
SELECT UserID, LoginTime, LogoutTime FROM ( SELECT ID, UserID ,LoginTime=CASE WHEN [Event] = 0 THEN EventTime END ,LogoutTime=CASE -- If the next Event by EventTime is a logout WHEN LEAD([Event], 1) OVER (PARTITION BY UserID ORDER BY EventTime) = 1 -- Then we pick up the corresponding EventTime THEN LEAD(EventTime, 1) OVER (PARTITION BY UserID ORDER BY EventTime) -- Otherwise logout time will be set to NULL END ,[Event] FROM #Events ) b -- Filter only on login events WHERE [Event] = 0 ORDER BY UserID, LoginTime; |
- Use the average duration of that user’s logins to predict an approximate LogoutTime.
- Assume the user is still logged in, so substitute GETDATE() for the LogoutTime.
Packing the Overlapping Login Intervals
Sometime back, a good friend of mine pointed me to an article that describes a way to pack overlapping intervals. That article is called Packing Intervals and it is by none other than SQL MVP and all-around guru, Mr. Itzik Ben-Gan. When I first read that article, I was impressed by the elegantly simple explanation for how this highly imaginative query works, so I won’t try to inadequately reproduce it here. What I can tell you is that it took me all of about three milliseconds (coincidentally the resolution of the SQL DATETIME data type) to realize that this was something I needed to retain in my tool box. Let’s look at how we would apply this technique to our sample data, by first putting our Example Query #3 (eliminating the spurious logins) into a Common Table Expression and then applying the Packing Intervals technique.Sample Query #4: Pack the Overlapping Intervals down to non-overlapping Events
|
1 2 3 4 5 6 7 8 9 10 11 12 13 14 15 16 17 18 19 20 21 22 23 24 25 26 27 28 29 30 31 32 33 34 35 36 37 38 39 40 41 42 43 44 45 46 47 48 49 50 51 52 53 54 55 56 57 58 59 60 61 62 |
WITH GroupedLogins AS ( -- Essentially the same as Sample Query #3 except a different filter SELECT UserID, LoginTime, LogoutTime FROM ( SELECT ID, UserID ,LoginTime=CASE WHEN [Event] = 0 THEN EventTime END ,LogoutTime=CASE -- If the next Event by EventTime is a logout WHEN LEAD([Event], 1) OVER (PARTITION BY UserID ORDER BY EventTime) = 1 -- Then we pick up the corresponding EventTime THEN LEAD(EventTime, 1) OVER (PARTITION BY UserID ORDER BY EventTime) -- Otherwise logout time will be set to NULL END ,[Event] FROM #Events ) a -- Filter only on login events that are not "open" (no logout) WHERE [Event] = 0 AND LogoutTime IS NOT NULL ), C1 AS ( -- Since the CTE above produces rows with a start and end date, we'll first unpivot -- those using CROSS APPLY VALUES and assign a type to each. The columns e and s will -- either be NULL (s NULL for an end date, e NULL for a start date) or row numbers -- sequenced by the time. UserID has been eliminated because we're looking for overlapping -- intervals across all users. SELECT ts, [Type] ,e=CASE [Type] WHEN 1 THEN NULL ELSE ROW_NUMBER() OVER (PARTITION BY [Type] ORDER BY LogoutTime) END ,s=CASE [Type] WHEN -1 THEN NULL ELSE ROW_NUMBER() OVER (PARTITION BY [Type] ORDER BY LoginTime) END FROM GroupedLogins CROSS APPLY (VALUES (1, LoginTime), (-1, LogoutTime)) a([Type], ts) ), C2 AS ( -- Add a row number ordered as shown SELECT C1.*, se=ROW_NUMBER() OVER (ORDER BY ts, [Type] DESC) FROM C1 ), C3 AS ( -- Create a grpnm that pairs the rows SELECT ts, grpnm=FLOOR((ROW_NUMBER() OVER (ORDER BY ts)-1) / 2 + 1) FROM C2 -- This filter is the magic that eliminates the overlaps WHERE COALESCE(s-(se-s)-1, (se-e)-e) = 0 ), C4 AS ( -- Grouping by grpnm restores the records to only non-overlapped intervals SELECT StartDate=MIN(ts), EndDate=MAX(ts) FROM C3 GROUP BY grpnm ) SELECT * FROM C4 ORDER BY StartDate; |
Results from C1:
|
1 2 3 4 5 6 7 8 9 |
ts Type e s 2013-09-01 17:00:00.000 -1 1 NULL 2013-09-01 19:10:00.000 -1 3 NULL 2013-09-01 18:20:00.000 -1 2 NULL 2013-09-02 11:45:00.000 -1 4 NULL 2013-09-01 16:15:00.000 1 NULL 1 2013-09-01 17:10:00.000 1 NULL 2 2013-09-01 18:00:00.000 1 NULL 3 2013-09-02 11:05:00.000 1 NULL 4 |
Results from C2:
|
1 2 3 4 5 6 7 8 9 |
ts Type e s se 2013-09-01 16:15:00.000 1 NULL 1 1 2013-09-01 17:00:00.000 -1 1 NULL 2 2013-09-01 17:10:00.000 1 NULL 2 3 2013-09-01 18:00:00.000 1 NULL 3 4 2013-09-01 18:20:00.000 -1 2 NULL 5 2013-09-01 19:10:00.000 -1 3 NULL 6 2013-09-02 11:05:00.000 1 NULL 4 7 2013-09-02 11:45:00.000 -1 4 NULL 8 |
Results from C3:
|
1 2 3 4 5 6 7 |
ts grpnm 2013-09-01 16:15:00.000 1 2013-09-01 17:00:00.000 1 2013-09-01 17:10:00.000 2 2013-09-01 19:10:00.000 2 2013-09-02 11:05:00.000 3 2013-09-02 11:45:00.000 3 |
Final Results from Sample Query #4:
|
1 2 3 4 |
StartDate EndDate 2013-09-01 16:15:00.000 2013-09-01 17:00:00.000 2013-09-01 17:10:00.000 2013-09-01 19:10:00.000 2013-09-02 11:05:00.000 2013-09-02 11:45:00.000 |
Sample Query #5: Simplify the Packing Method by using our logins/logouts directly
|
1 2 3 4 5 6 7 8 9 10 11 12 13 14 15 16 17 18 19 20 21 22 23 24 25 26 27 28 29 30 31 32 33 34 35 36 37 38 39 40 41 42 43 |
DELETE FROM #Events WHERE ID IN (9,10); WITH C1 AS ( -- It is no longer necessary to CROSS APPLY VALUES to UNPIVOT. The columns e and s will -- either be NULL (s NULL for an end date, e NULL for a start date) or row numbers -- sequenced by the time. UserID has been eliminated because we're looking for overlapping -- intervals across all users. Now we're using the native event type [Event] instead of -- creating one during the UNPIVOT. SELECT EventTime, [Event] ,e=CASE [Event] WHEN 0 THEN NULL ELSE ROW_NUMBER() OVER (PARTITION BY [Event] ORDER BY EventTime) END ,s=CASE [Event] WHEN 1 THEN NULL ELSE ROW_NUMBER() OVER (PARTITION BY [Event] ORDER BY EventTime) END FROM #Events ), C2 AS ( -- Add a row number ordered as shown SELECT C1.*, se=ROW_NUMBER() OVER (ORDER BY EventTime, [Event] DESC) FROM C1 ), C3 AS ( -- Create a grpnm that pairs the rows SELECT EventTime, grpnm=FLOOR((ROW_NUMBER() OVER (ORDER BY EventTime)-1) / 2 + 1) FROM C2 -- This filter is the magic that eliminates the overlaps WHERE COALESCE(s-(se-s)-1, (se-e)-e) = 0 ), C4 AS ( -- Grouping by grpnm restores the records to only non-overlapped intervals SELECT StartDate=MIN(EventTime), EndDate=MAX(EventTime) FROM C3 GROUP BY grpnm ) SELECT * FROM C4 ORDER BY StartDate; Here we have used the native event type, instead of constructing one using CROSS APPLY VALUES as Mr. Ben-Gan did in his original C1 CTE. The results from this query are shown below. |
Results from Sample Query #5:
|
1 2 3 |
StartDate EndDate 2013-09-01 15:33:00.000 2013-09-01 19:10:00.000 2013-09-02 11:05:00.000 2013-09-02 11:45:00.000 |
Converting Packed Intervals to the Corresponding Gaps
Once we have our packed intervals (“islands”) it is simple enough to add just a little bit of code to convert these into gaps. We draw upon a previous Simple Talk article called The SQL of Gaps and Islands in Sequence Numbers and look for the CROSS APPLY VALUES method to convert islands to gaps. We will add this technique to Sample Query #5 to get to:Sample Query #6: Convert Packed Intervals into Gaps Between them
|
1 2 3 4 5 6 7 8 9 10 11 12 13 14 15 16 17 18 19 20 21 22 23 24 25 26 27 28 29 30 31 32 33 34 35 36 37 38 39 40 41 42 43 44 45 46 47 48 49 |
WITH C1 AS ( -- The columns e and s will either be NULL (s NULL for an end date, e NULL for a start date) -- or row numbers sequenced by the time. UserID has been eliminated because we're looking -- for overlapping intervals across all users. Now we're using the native event type [Event] -- instead of creating one during the UNPIVOT. SELECT EventTime, [Event] ,e=CASE [Event] WHEN 0 THEN NULL ELSE ROW_NUMBER() OVER (PARTITION BY [Event] ORDER BY EventTime) END ,s=CASE [Event] WHEN 1 THEN NULL ELSE ROW_NUMBER() OVER (PARTITION BY [Event] ORDER BY EventTime) END FROM #Events ), C2 AS ( -- Add a row number ordered as shown SELECT C1.*, se=ROW_NUMBER() OVER (ORDER BY EventTime, [Event] DESC) FROM C1 ), C3 AS ( -- Create a grpnm that pairs the rows SELECT EventTime, grpnm=FLOOR((ROW_NUMBER() OVER (ORDER BY EventTime)-1) / 2 + 1) FROM C2 -- This filter is the magic that eliminates the overlaps WHERE COALESCE(s-(se-s)-1, (se-e)-e) = 0 ), C4 AS ( -- Grouping by grpnm restores the records to only non-overlapped intervals SELECT StartDate=MIN(EventTime), EndDate=MAX(EventTime) FROM C3 GROUP BY grpnm ) -- CROSS APPLY VALUES to convert islands to gaps SELECT StartTime=MIN(EventTime), EndTime=MAX(EventTime) FROM ( SELECT EventTime ,rn=ROW_NUMBER() OVER (ORDER BY EventTime)/2 FROM C4 a CROSS APPLY (VALUES (StartDate), (EndDate)) b(EventTime) ) a GROUP BY rn HAVING COUNT(*) = 2 ORDER BY StartTime; Comparing the results of this query with the Results from Sample Query #5, we can see by inspection that the row returned is the gap between the two islands. |
Results from Sample Query #6:
|
1 2 |
StartTime EndTime 2013-09-01 19:10:00.000 2013-09-02 11:05:00.000 |
Building a Test Harness
Now that we have a way to calculate gaps between overlapping intervals, we want to make sure that the code we’ve built will scale to large row sets in a reasonable fashion. To do this, we must build a test harness with a realistic number of rows. We can simulate the duration of a login by starting the login at a particular time of day and then assume that the user was logged in for a random period of time. In SQL, we can generate uniform random numbers like this:|
1 |
SELECT 10+ABS(CHECKSUM(NEWID()))%120 |
|
1 2 3 4 5 6 7 8 9 10 11 12 13 |
CREATE FUNCTION dbo.RN_NORMAL ( @Mean FLOAT ,@StDev FLOAT ,@URN1 FLOAT ,@URN2 FLOAT ) RETURNS FLOAT WITH SCHEMABINDING AS BEGIN -- Based on the Box-Muller Transform RETURN (@StDev * SQRT(-2 * LOG(@URN1))*COS(2*ACOS(-1.)*@URN2)) + @Mean END |
|
1 2 3 4 5 6 7 8 9 10 11 12 13 14 15 16 17 18 19 20 21 22 23 24 25 26 27 28 29 30 31 32 33 34 35 36 37 38 |
DECLARE @StartDate DATETIME = '2005-01-01' -- 500 days x 1000 users x 2 endpoints = 1,000,000 rows ,@UserIDs INT = 1000 ,@Days INT = 500 ,@MeanLoginSeconds INT = 240 ,@StdDevLoginSeconds INT = 60; WITH Tally (n) AS ( SELECT TOP ( SELECT CASE WHEN @UserIDs > @Days THEN @UserIDs ELSE @Days END ) ROW_NUMBER() OVER (ORDER BY (SELECT NULL)) FROM sys.all_columns a CROSS JOIN sys.all_columns b ) INSERT INTO #Events SELECT UserID=f.n, EventTime, [Event] -- Create 2 uniform random numbers FROM (SELECT RAND(CHECKSUM(NEWID()))) a(URN1) CROSS APPLY (SELECT RAND(CHECKSUM(NEWID()))) b(URN2) -- Create 1 Normally-distributed random number from the 2 URNs using the -- using the Box-Muller transform function CROSS APPLY ( SELECT dbo.RN_NORMAL(@MeanLoginSeconds, @StdDevLoginSeconds, URN1, URN2) ) c(NRN) -- Use our Tally table to generate the required number of @Days then convert to a date CROSS APPLY (SELECT n FROM Tally WHERE n BETWEEN 1 AND @Days) d CROSS APPLY (SELECT DATEADD(day, d.n-1, @StartDate)) e([Date]) -- Use our Tally table to generate the required number of @users and logins/logouts CROSS APPLY (SELECT n FROM Tally WHERE n BETWEEN 1 AND @UserIDs) f CROSS APPLY (SELECT DATEADD(second, ABS(CHECKSUM(NEWID()))%84000, e.[Date])) g(LoginStart) CROSS APPLY ( VALUES (0, LoginStart),(1, DATEADD(second, NRN, LoginStart)) ) h([Event], EventTime); |
Test Harness 1 (2008).sql– tests 2 queries which are like Sample Query #5 plus the additional code to convert those islands to gaps (Sample Query #6).Test Harness 2 (2012).sql– tests 3 queries which are like Sample Query #3 (removing the logins with missing logouts), Sample Query #4 (to calculate the packed intervals) and finally with the additional code to convert those islands into gaps.
|
1 2 3 4 5 6 7 8 |
WITH Logouts AS ( SELECT *, rn=ROW_NUMBER() OVER (ORDER BY EventTime) FROM #Events WHERE [Event] = 1 ) DELETE FROM Logouts WHERE rn % 300 = 2; |
Performance Results
Using Test Harness 1 (2008).sql (run in SQL 2008) we can demonstrate that the additional time for CPU and Elapsed run times when adding the CROSS APPLY VALUES Islands to Gaps method to the interval packing is nearly insignificant. Together the solutions both scale quite linearly and are fairly reasonable when there are no missing logouts.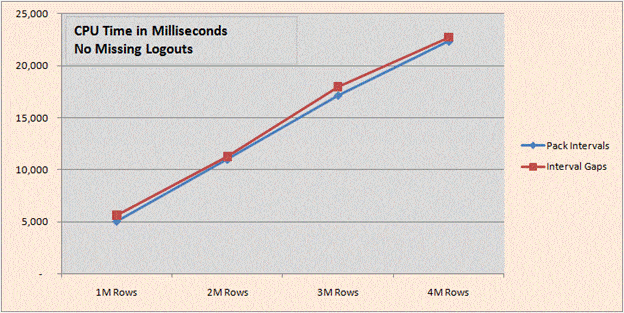 The result below at 4M rows for elapsed time (Interval Gaps less than Pack Intervals) can only be explained by an increasing amount of parallelism introduced by SQL Server into the query.
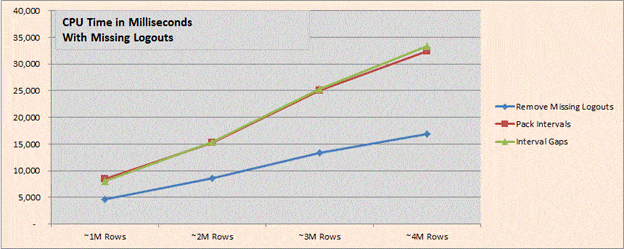
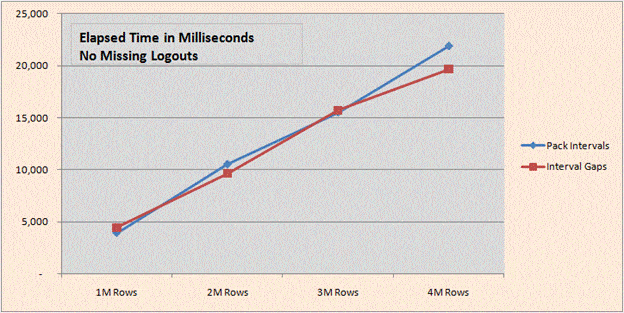 We see a similar story when reviewing the results when there are missing logouts (using Test Harness 2 (2012).sql (run in SQL 2012). Simply needing to remove the missing logouts takes slightly more than 50% of the CPU, but when we layer calculating the gaps on top of the packing algorithm, that additional work is quite minimal.
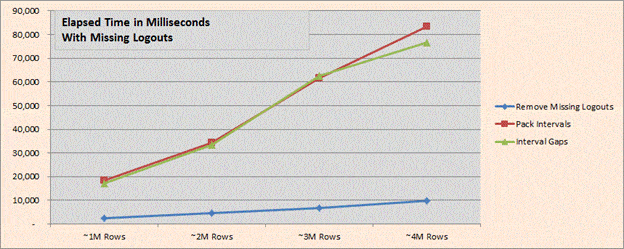
 Elapsed times tell a similar story except that the amount of time for removing the open-ended logins does not comprise nearly as large a percentage of the overall time. Nonetheless, both interval packing and calculating the gaps between them scales quite linearly.
 Note that test results for the cases of no vs. missing logouts were run on different machines due to the need for SQL 2012 for the latter, so the CPU/Elapsed times recorded may not be comparable in terms of raw magnitude. Test machines:
- No Missing Logouts: Windows 7 Professional and SQL 2008 R2 (both 64 bit), Dell Inspiron laptop w-Intel Core i5-2430M @ 2.4 GHz, 8GB RAM
- Missing Logouts: Windows 7 Enterprise and SQL 2012 (both 64 bit), Lenovo laptop w-Intel Core i5-3230M @ 2.60 GHz, 12GB RAM
Conclusion
The important concepts we have demonstrated in this article are:- Combining rows where login and logout events are paired.
- A fast solution using the SQL 2012 analytic function LEAD for combining rows where login and logout events are paired, but some of the logout events are missing.
- The excellent solution proposed by SQL MVP Itzik Ben-Gan for packing intervals, with modifications to support both of the above cases.
- Using the CROSS APPLY VALUES approach to convert islands (packed intervals) to gaps (the periods of no login activity).
- Finally, and very importantly, that these solutions seem linearly scalable to multi-million row sets.
Further Reading
Dealing with event intervals is a fascinating and challenging problem in SQL. If you are interested in pursuing this further, I strongly recommend that you take a look at some of the links below. They provide even more advanced, high-performing techniques for dealing with time intervals.- Packing Intervals by Itzik Ben-Gan
- Interval Queries in SQL Server by Itzik Ben-Gan
- Intervals and Counts, Part 1 by Itzik Ben-Gan
- Intervals and Counts, Part 2 by Itzik Ben-Gan
- Intervals and Counts, Part 3 by Itzik Ben-Gan
- A Static Relational Interval Tree by Laurent Martin
- Advanced interval queries with the Static Relational Interval Tree by Laurent Martin
- Using the Static Relational Interval Tree with time intervals by Laurent Martin
FAQs
1. How do I find gaps between overlapping time intervals in SQL Server?
Two-step approach: (1) pack the overlapping intervals into their continuous-range equivalents by sorting on start time and collapsing any pair where the next start falls before the current end; (2) convert those packed ranges to their complement – the gaps – by computing the range between the end of one packed interval and the start of the next. This article includes complete T-SQL for both steps. The first step (packing) is a classic pattern; the second step (inverting packed intervals to gaps) reuses gaps-and-islands machinery applied to the packed result. The technique works for any overlapping interval type: login sessions, vehicle events, hotel occupancy, factory uptime.
2. What is interval packing in SQL Server?
Interval packing is the task of collapsing a set of overlapping or adjacent intervals into the minimum set of non-overlapping intervals that cover the same range. Given (1-5, 3-7, 10-12), packing produces (1-7, 10-12). The standard T-SQL approach uses window functions: compute a running maximum of end times ordered by start time, then identify interval boundaries where the next start exceeds the running max. Packing is the prerequisite for many ‘when is something happening’ queries – once intervals are packed, questions about gaps, coverage, and overlaps become straightforward.
3. How do I find periods when no users are logged in using SQL?
Pack the overlapping login intervals into continuous ‘at least one user logged in’ ranges, then compute the gaps between those ranges. Each gap represents a period when no users were logged in. In T-SQL: use a common table expression to sort login rows by start time, compute a running maximum of logout times with MAX() OVER, identify interval boundaries, and then compute the complement as the difference between adjacent packed ranges. The same pattern works for vehicle fleet ‘all idle’ periods, factory ‘all lines down’ periods, and any concurrency-inactive reporting question.
4. What is the difference between gaps-and-islands and interval packing in SQL Server?
Gaps-and-islands works on discrete sequences of values (typically integers or dates at a fixed step): identifying runs of consecutive values and the missing values between them. Interval packing works on continuous ranges: collapsing overlapping or adjacent ranges into their minimal covering set. The two techniques are related – interval packing uses gaps-and-islands machinery internally once intervals are converted to their per-unit form (the Unpack/Pack technique) – but they solve different problems. Use gaps-and-islands when your data is a sequence of discrete values. Use interval packing when your data is a set of ranges that can overlap.
This document contains proprietary information and is protected by copyright law.
Copyright © 2026 Red Gate Software Limited. All rights reserved

Load comments