

In a past article on the bcp command-line utility, I demonstrated how to use the utility to bulk load external data into a SQL Server database. The advantage of using bcp is that you can quickly and easily import data from a windows command-line process without having to open an Integrated Development Environment (IDE) such as SQL Server Management Studio, or use SQLCMD, to issue a Transact-SQL statement. However, there might be times when you want to use Transact-SQL to bulk load data, in which case, you can use one of two statements supported by SQL Server:
BULK INSERT-available in SQL Server 2005 and 2008INSERT...SELECT * FROM OPENROWSET(BULK...)– available in SQL Server 2005 and 2008.
|
1 2 3 4 5 6 7 8 9 10 11 12 13 14 15 16 17 18 19 |
USE master; IF DB_ID('EmployeeDB') IS NOT NULL DROP DATABASE EmployeeDB; CREATE DATABASE EmployeeDB; GO USE EmployeeDB; IF OBJECT_ID ('Employees', 'U') IS NOT NULL DROP TABLE dbo.Employees; CREATE TABLE dbo.Employees ( EmployeeID INT NOT NULL, FirstName NVARCHAR(50) NOT NULL, LastName NVARCHAR(50) NOT NULL, JobTitle NVARCHAR(50) NOT NULL, City NVARCHAR(30) NOT NULL, StateProvince NVARCHAR(50) NOT NULL, CountryRegion NVARCHAR(50) NOT NULL, CONSTRAINT PK_Employees PRIMARY KEY CLUSTERED (EmployeeID ASC) ); |
|
1 |
bcp "SELECT BusinessEntityID, FirstName, LastName, JobTitle, City, StateProvinceName, CountryRegionName FROM AdventureWorks2008.HumanResources.vEmployee ORDER BY BusinessEntityID" queryout C:\Data\EmployeeData_c.dat -c -t, -r \r\n -S localhost\SqlSrv2008 -T |
(For these commands, you’ll need to change the location of the file and the name of the server, you may also need to change ‘AdventureWorks2008’ to the current name of the database: The BusinessEntityID, introduced for Entity Framework, has now been changed back to EmployeeID so you might need to rename this too!)
The second bcp command creates a format file named EmployeeFormat_c.fmt, based on character data:|
1 |
bcp EmployeeDB.dbo.Employees format nul -c -t, -r \r\n -f C:\Data\EmployeeFormat_c.fmt -S localhost\SqlSrv2008 -T |
|
1 |
bcp "SELECT BusinessEntityID, FirstName, LastName, JobTitle, City, StateProvinceName, CountryRegionName FROM AdventureWorks2008.HumanResources.vEmployee ORDER BY BusinessEntityID" queryout C:\Data\EmployeeData_n.dat -N -S localhost\SqlSrv2008 -T |
|
1 |
bcp EmployeeDB.dbo.Employees format nul -N -f C:\Data\EmployeeFormat_n.fmt -S localhost\SqlSrv2008 -T |
NOTE: For most of the examples, you’ll need to truncate the Employees table after each bulk load to prevent primary key errors when loading the data. This is because you’re loading the same source data into the same target table for each example.
BULK INSERT
The first statement we’ll look at is BULK INSERT, which lets you import data from a data file into a table or view. You can specify the format of the imported data, based on how that data is stored in the file. In the following example, I import the data from the EmployeeData_c.dat file into the Employees table:|
1 2 3 4 5 6 7 8 9 |
BULK INSERT EmployeeDB.dbo.Employees FROM 'C:\Data\EmployeeData_c.dat' WITH ( DATAFILETYPE = 'char', FIELDTERMINATOR = ',', ROWTERMINATOR = '\r\n' ); |
|
1 2 3 4 5 6 7 |
BULK INSERT EmployeeDB.dbo.Employees FROM 'C:\Data\EmployeeData_c.dat' WITH ( FORMATFILE = 'C:\Data\EmployeeFormat_c.fmt' ); |
|
1 2 3 4 5 6 7 |
BULK INSERT EmployeeDB.dbo.Employees FROM 'C:\Data\EmployeeData_n.dat' WITH ( DATAFILETYPE = 'widenative' ); |
|
1 2 3 4 5 6 7 |
BULK INSERT EmployeeDB.dbo.Employees FROM 'C:\Data\EmployeeData_n.dat' WITH ( FORMATFILE = 'C:\Data\EmployeeFormat_n.fmt' ); |
INSERT…SELECT
Starting with SQL Server 2005, the OPENROWSET function supports bulk operations through the use of the BULK provider. You can use the function and provider within an INSERT…SELECT statement to bulk load data from a data file into a table or view, just like you saw with the BULK INSERT statement. In the following INSERT…SELECT statement, I call the OPENROWSET function and BULK provider in order import data from the EmployeeData_c.dat file:|
1 2 3 4 5 6 7 8 |
INSERT INTO EmployeeDB.dbo.Employees SELECT * FROM OPENROWSET(BULK 'c:\data\EmployeeData_c.dat', FORMATFILE = 'C:\Data\EmployeeFormat_c.fmt' ) AS e; |
|
1 2 3 4 5 6 7 |
INSERT INTO EmployeeDB.dbo.Employees SELECT * FROM OPENROWSET(BULK 'c:\data\EmployeeData_n.dat', FORMATFILE = 'C:\Data\EmployeeFormat_n.fmt') AS e; |
Performance
When bulk importing data into a SQL Server database, there are several steps you can take to maximize performance. One of these steps I mentioned earlier, and that is, when possible, work with data in SQL Server native format. Native format retains SQL Server’s native data types. Even if you use wide native format (preserving the Unicode), as I did in several of the examples above, you’re still taking advantage of the non-character native data types. Of course, you can’t always control whether the source file is in native or wide native format, but there are other steps you can take to maximize performance. In this section, we’ll look at several of those steps and review examples that demonstrate how to implement them. NOTE: Microsoft documentation on bulk loading operations can often be confusing, especially when trying to understand the BULK INSERT and the SELECT…INTO statements-and the differences between them. In researching these statements, you might find contradictory or inaccurate information, or information that simply doesn’t make sense. Whenever you’re developing a bulk load solution, you’re best bet is to test different scenarios and see for yourself what works best.Table Locking
One way you can help to improve performance in your bulk load operations is to specify table locking for the duration of the data load. You can do this by including the TABLOCK argument with your statement. The argument issues a bulk update (BU) lock on the table. In the following BULK INSERT statement, I’ve included the TABLOCK argument in the WITH clause:|
1 2 3 4 5 6 7 8 |
BULK INSERT EmployeeDB.dbo.Employees FROM 'C:\Data\EmployeeData_n.dat' WITH ( FORMATFILE = 'C:\Data\EmployeeFormat_n.fmt', TABLOCK ); |
|
1 2 3 4 5 6 7 |
INSERT INTO EmployeeDB.dbo.Employees WITH(TABLOCK) SELECT * FROM OPENROWSET(BULK 'C:\Data\EmployeeData_n.dat', FORMATFILE = 'C:\Data\EmployeeFormat_n.fmt') AS e; |
Minimal Logging
Another method you can use to maximize performance is to minimally log the operation when bulk loading data. Minimal logging can make bulk load operations more efficient and minimize the risk that the transaction log will fill up. To minimally log a bulk load operation, the TABLOCK option must be specified and the table must not be being replicated. In addition, the operation can be minimally logged only under one of the following conditions:- If the table has no indexes, the data pages can be minimally logged.
- If the table has no clustered indexes, has nonclustered indexes, and is empty, data pages and index pages can be minimally logged.
- If the table has no clustered indexes, has nonclustered indexes, and has data, data pages can be minimally logged but index pages cannot.
- If the table has a clustered index but is empty, data pages and indexed pages can be minimally logged. (Both types of pages are fully logged whenever the table contains data.)
|
1 2 3 4 5 6 7 8 9 10 11 12 13 14 |
ALTER DATABASE EmployeeDB SET RECOVERY BULK_LOGGED; BULK INSERT EmployeeDB.dbo.Employees FROM 'C:\Data\EmployeeData_n.dat' WITH ( FORMATFILE = 'C:\Data\EmployeeFormat_n.fmt', TABLOCK ); ALTER DATABASE EmployeeDB SET RECOVERY FULL; |
|
1 2 3 4 5 6 7 8 9 10 11 12 13 |
ALTER DATABASE EmployeeDB SET RECOVERY BULK_LOGGED; INSERT INTO EmployeeDB.dbo.Employees WITH(TABLOCK) SELECT * FROM OPENROWSET(BULK 'C:\Data\EmployeeData_n.dat', FORMATFILE = 'C:\Data\EmployeeFormat_n.fmt') AS e ALTER DATABASE EmployeeDB SET RECOVERY FULL; |
Dropping Indexes
Bulk load operations can be affected by the indexes defined on a table, not only with regard to minimally logging your operations, but also when you’re importing a large amount of data compared to the amount already in the table. In such cases, it is sometimes useful to drop the indexes before you load the data, and then re-create those indexes after the operation has completed. Dropping indexes can significantly improve the performance of a bulk load operation. However, it’s not always a clear-cut decision when to drop them. If you’re importing a small amount of data compared to the amount of data in the table, then you probably shouldn’t drop the indexes; otherwise, you’ll spend more time rebuilding the indexes than it takes to load the data. However, when the situation is reversed, you’ll often benefit from dropping the indexes. In the following example, I first include an ALTER TABLE statement that drops the primary key constraint (and its associated clustered index) and then include a second ALTER TABLE statement that re-creates the constraint and its index:|
1 2 3 4 5 6 7 8 9 10 11 12 13 14 15 16 17 18 19 20 |
ALTER DATABASE EmployeeDB SET RECOVERY BULK_LOGGED; IF OBJECT_ID ('PK_Employees', 'PK') IS NOT NULL ALTER TABLE Employees DROP CONSTRAINT PK_Employees; BULK INSERT EmployeeDB.dbo.Employees FROM 'C:\Data\EmployeeData_n.dat' WITH ( FORMATFILE = 'C:\Data\EmployeeFormat_n.fmt', TABLOCK ); ALTER TABLE Employees ADD CONSTRAINT PK_Employees PRIMARY KEY CLUSTERED (EmployeeID); ALTER DATABASE EmployeeDB SET RECOVERY FULL; |
|
1 2 3 4 5 6 7 8 9 10 11 12 13 14 15 16 17 18 19 20 |
ALTER DATABASE EmployeeDB SET RECOVERY BULK_LOGGED; IF OBJECT_ID ('PK_Employees', 'PK') IS NOT NULL ALTER TABLE Employees DROP CONSTRAINT PK_Employees; INSERT INTO EmployeeDB.dbo.Employees WITH(TABLOCK) SELECT * FROM OPENROWSET(BULK 'C:\Data\EmployeeData_n.dat', FORMATFILE = 'C:\Data\EmployeeFormat_n.fmt') AS e ALTER TABLE Employees ADD CONSTRAINT PK_Employees PRIMARY KEY CLUSTERED (EmployeeID); ALTER DATABASE EmployeeDB SET RECOVERY FULL; |
Ordering
By default, SQL Server assumes that the source data is unordered when you perform a bulk load operation. However, in some cases, you can improve the performance of that operation by specifying the sort order of the imported data. But you can do this only if the target table has a clustered index and the source data file is sorted in the same way as defined by the index. If these conditions are met, you can add an ORDER option to your bulk load statement to help increase the speed of the operation. The ORDER option specifies the sort order of the incoming data. The columns listed along with that option should match the columns as defined in the clustered index and be in the same order. In the following BULK INSERT statement, I’ve added an ORDER option to the WITH clause and specified the EmployeeID column as the sort column:|
1 2 3 4 5 6 7 8 9 10 11 12 13 14 15 |
ALTER DATABASE EmployeeDB SET RECOVERY BULK_LOGGED; BULK INSERT EmployeeDB.dbo.Employees FROM 'C:\Data\EmployeeData_n.dat' WITH ( FORMATFILE = 'C:\Data\EmployeeFormat_n.fmt', TABLOCK, ORDER (EmployeeID ASC) ); ALTER DATABASE EmployeeDB SET RECOVERY FULL; |
|
1 2 3 4 5 6 7 8 9 10 11 12 13 14 15 |
ALTER DATABASE EmployeeDB SET RECOVERY BULK_LOGGED; INSERT INTO EmployeeDB.dbo.Employees WITH(TABLOCK) SELECT * FROM OPENROWSET(BULK 'C:\Data\EmployeeData_n.dat', FORMATFILE = 'C:\Data\EmployeeFormat_n.fmt', ORDER (EmployeeID ASC) ) AS e; ALTER DATABASE EmployeeDB SET RECOVERY FULL; |
|
1 2 3 4 5 6 7 8 9 10 11 12 13 14 15 16 17 18 |
ALTER DATABASE EmployeeDB SET RECOVERY BULK_LOGGED; DBCC TRACEON(610); INSERT INTO EmployeeDB.dbo.Employees WITH(TABLOCK) SELECT * FROM OPENROWSET(BULK 'C:\Data\EmployeeData_n.dat', FORMATFILE = 'C:\Data\EmployeeFormat_n.fmt', ORDER (EmployeeID ASC) ) AS e; DBCC TRACEOFF(610); ALTER DATABASE EmployeeDB SET RECOVERY FULL; |
Constraints and Triggers
When running BULK INSERT and INSERT…SELECT statements, you can control whether check constraints and triggers are enforced during the bulk load operation. By disabling the constraints and triggers, you can see an improvement in the bulk load operations. However, if you do, you must be sure to follow up on any critical operations the constraints and triggers perform, after you’ve completed your bulk load operation. When it comes to check constraints and triggers, the default behavior of the BULK INSERT and INSERT…SELECT statement is different:- By default, the BULK INSERT statement ignores constraints and disables triggers.
- By default, the INSERT…INTO statement executes check constraints and triggers.
|
1 2 3 4 5 6 7 8 9 10 11 12 13 14 15 16 17 18 19 20 21 22 23 |
ALTER DATABASE EmployeeDB SET RECOVERY BULK_LOGGED; IF OBJECT_ID ('PK_Employees', 'PK') IS NOT NULL ALTER TABLE Employees DROP CONSTRAINT PK_Employees; BULK INSERT EmployeeDB.dbo.Employees FROM 'C:\Data\EmployeeData_n.dat' WITH ( FORMATFILE = 'C:\Data\EmployeeFormat_n.fmt', TABLOCK, CHECK_CONSTRAINTS, FIRE_TRIGGERS ); ALTER TABLE Employees ADD CONSTRAINT PK_Employees PRIMARY KEY CLUSTERED (EmployeeID); ALTER DATABASE EmployeeDB SET RECOVERY FULL; |
|
1 2 3 4 5 6 7 8 9 10 11 12 13 14 15 16 17 18 19 20 21 |
ALTER DATABASE EmployeeDB SET RECOVERY BULK_LOGGED; IF OBJECT_ID ('PK_Employees', 'PK') IS NOT NULL ALTER TABLE Employees DROP CONSTRAINT PK_Employees; INSERT INTO EmployeeDB.dbo.Employees WITH(TABLOCK, IGNORE_CONSTRAINTS, IGNORE_TRIGGERS) SELECT * FROM OPENROWSET(BULK 'C:\Data\EmployeeData_n.dat', FORMATFILE = 'C:\Data\EmployeeFormat_n.fmt') AS e ALTER TABLE Employees ADD CONSTRAINT PK_Employees PRIMARY KEY CLUSTERED (EmployeeID); ALTER DATABASE EmployeeDB SET RECOVERY FULL; |
Conclusion
As you can see, trying to determine the best way to bulk load data can be a complicated process. It often takes testing various scenarios to come up with the best approach. In addition, it’s not always clear, based on Microsoft documentation, whether to use BULK INSERT or INSERT…SELECT * FROM OPENROWSET(BULK…) when importing external data. Some information indicates that INSERT…SELECT will not support concurrent bulk load operations into a single table. (I haven’t tested this scenario.) It also appears that INSERT…SELECT doesn’t let you specify multiple batches in a single operation (no BATCHSIZE option). Even so, for most bulk load operations, you’ll probably do fine with either statement, as long as you take other steps to improve performance. You’ll have to take each operation on a case-by-case basis and determine what works best for your specific circumstances.Appendix
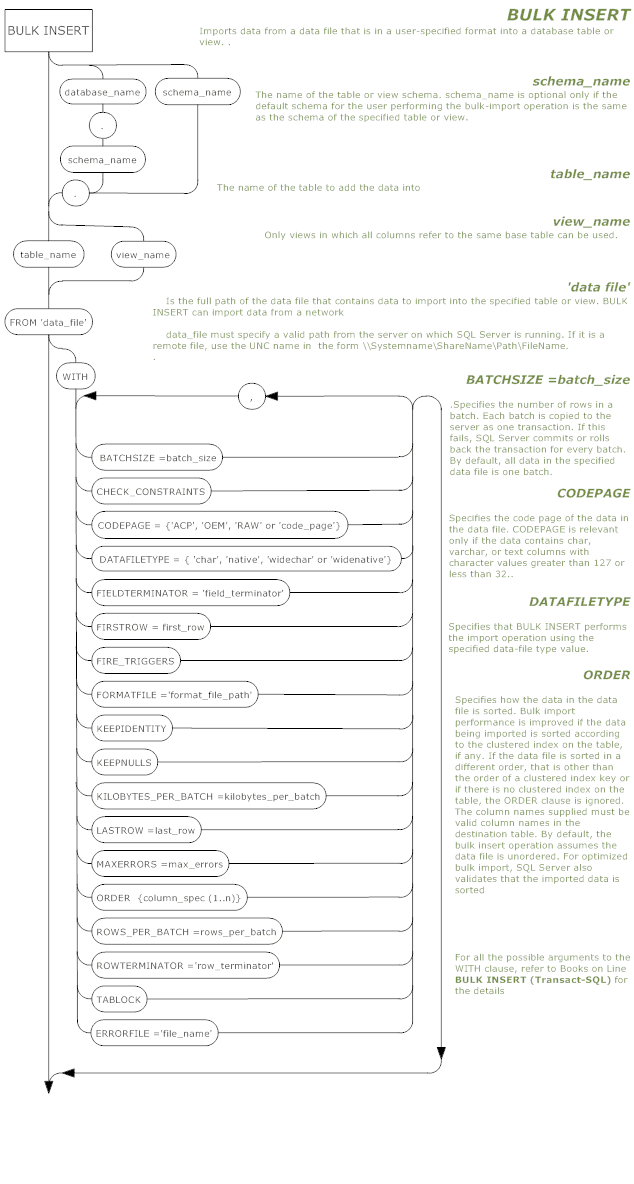
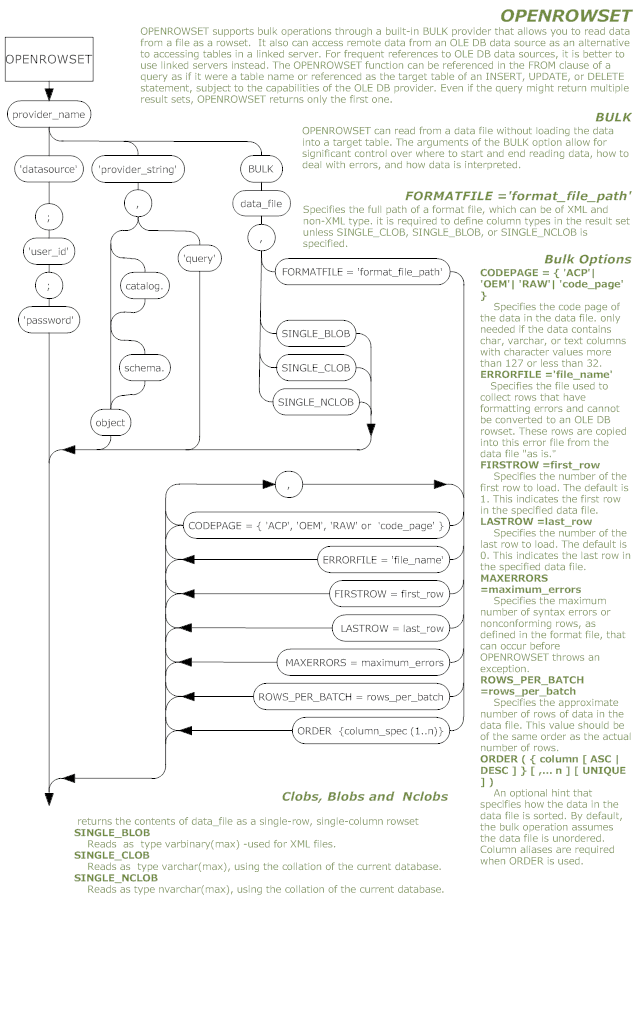
Here are the railroad diagrams forBulk Insert and OpenRowSet. The PDF versions are attached as files to this article. For completeness, the OpenRowSet diagram shows all the available syntax as well as the BULK functionality.
BULK INSERT
OpenRowSet
FAQs
1. How do I use BULK INSERT in SQL Server?
BULK INSERT loads data from a file into a SQL Server table. Minimal syntax: BULK INSERT dbo.TargetTable FROM ‘C:\data\source.csv’ WITH (FIELDTERMINATOR = ‘,’, ROWTERMINATOR = ‘\n’, FIRSTROW = 2). The WITH options handle field separators, row separators, header-row skipping, data file type (CHAR, WIDECHAR, NATIVE, WIDENATIVE), codepage, format file references for complex layouts, and error handling (MAXERRORS, ERRORFILE). The statement requires INSERT permission on the target table and ADMINISTER BULK OPERATIONS server permission. The file path is evaluated on the SQL Server machine (not the client running SSMS) – for files on the client machine, copy to a SQL Server-accessible location first.
2. What is the difference between BULK INSERT and OPENROWSET BULK in SQL Server?
Both load data from external files or sources. BULK INSERT is a dedicated statement for loading from file into a table – terse syntax, optimised for the common case. OPENROWSET with the BULK provider is used inside an INSERT…SELECT statement – more flexible because the SELECT can include WHERE clauses, joins, type conversions, and column-level transformations between source and target. OPENROWSET BULK is the right choice when you need to filter or transform the data during load; BULK INSERT is simpler when you’re doing a direct file-to-table load with no transformation. Performance is broadly comparable when both are configured correctly for bulk load (TABLOCK, minimal logging).
3. How do I enable minimal logging for a bulk insert in SQL Server?
Four conditions must all be met for minimal logging: (1) the database is in Simple or Bulk-Logged recovery model; (2) the target table has TABLOCK specified in the bulk-load statement; (3) the target is a heap OR the target is a clustered table that is empty (or the load is into an empty partition); (4) the table does NOT have non-clustered indexes (or an empty target with trace flag 610 for specific edge cases). When all four hold, SQL Server logs only page allocations and metadata rather than full row content, reducing log volume by 10-100x. For production systems in Full recovery, switch to Bulk-Logged for the duration of the load then back to Full – with the understanding that point-in-time recovery for the load window is lost.
4. Should I drop indexes before a bulk insert in SQL Server?
Usually yes when loading 20% or more of the existing table’s row count, no when loading a smaller percentage. Dropping non-clustered indexes before load and rebuilding after trades the per-row index maintenance cost during load (N indexes × N rows of work) for a single bulk rebuild after (much faster). The break-even point varies by row size, index count, and data distribution – for very wide tables with many indexes, drop-and-rebuild wins even at 5-10% loads; for narrow tables with one or two indexes, keep-indexes wins even at 30-50% loads. The clustered index is typically left in place because dropping it physically reorganises the table. Test on representative data rather than relying on the percentage rule alone.
This document contains proprietary information and is protected by copyright law.
Copyright © 2026 Red Gate Software Limited. All rights reserved


Load comments