

|
1 |
YEAR_Area_Primary Asset_Space Separated Tag List_PIC0000000.jpg |
- “Year” is the year the picture was taken.
- “Area” is a broad container of things that I want to keep up with, in this case it is like the Magic Kingdom, or Hollywood Studios.
- “Primary Asset” is the attraction, or some aspect of the parks that best identifies what the picture is about.
- “Space Separated Tag List” is a set of Assets or descriptive words to help find pictures.
- “PIC0000000” is a picture number that I append to the end of the picture. Working on the local machine, Windows won’t let you do some things in File explore directly (like rename a file, though you can delete or move the file out of a directory in the filetable). So if you need to do something to a file (like fix the name to meet your standard, or add tags), you may have to copy it out of the folder, modify the filename, then put it back into the SQL Server file share. That is why I append PIC0000000 to the file name and will use it as my connection to the data. If you move the file from the filetable and put it back, it can have a different stream_id as the internal key but the PIC tag never changes.
|
1 2 |
2010_MagicKingdom_CinderellaCastle_Front Dusk_PIC0020116.jpg 2019 MagicKingdom_HauntedMansion_Exterior CinderellaCastle ViewOtherAsset_PIC0000200.jpg |
ViewOtherAsset to see all of the assets where you can see another asset from it. In essence, the tagging process should be the hardest part of the process (and one day I will start to explore machine learning and see if I can auto-tag pictures, but that is WAY beyond what I am good at right now!)
Note: I am going to assume you have your server configured for filestream and access set up for filetables. If not, see this Microsoft Docs page (https://docs.microsoft.com/en-us/sql/relational-databases/blob/enable-the-prerequisites-for-filetable). I will use non-transactional access, using a 2019 Express Edition SQL Server, perfect for a single user hobby database. (As I refine the code, I will be configuring it for proper concurrency, in case anyone else wishes to use the project.)
To start, I will create a database with filestream:
|
1 2 3 4 5 6 7 8 9 10 11 12 13 14 15 16 17 |
CREATE DATABASE [DemoFiletable] ON PRIMARY NAME = N'DemoFiletable', FILENAME = N'C:\Program Files\Microsoft SQL Server\MSSQL15.THEMEPARK\MSSQL\DATA\DemoFiletable.mdf' , SIZE = 10000KB , MAXSIZE = UNLIMITED, FILEGROWTH = 10000KB ), FILEGROUP [FilestreamData] CONTAINS FILESTREAM DEFAULT ( NAME = N'FilestreamDataFile1', FILENAME = N'c:\sql\DemoFiletableFilestream' , MAXSIZE = UNLIMITED) LOG ON ( NAME = N'DemoFiletable_log', FILENAME = N'C:\Program Files\Microsoft SQL Server\MSSQL15.THEMEPARK\MSSQL\DATA\DemoFiletable_log.ldf' , SIZE = 335872KB , MAXSIZE = 2048GB , FILEGROWTH = 65536KB ) WITH CATALOG_COLLATION = DATABASE_DEFAULT; ALTER DATABASE DemoFiletable SET FILESTREAM( NON_TRANSACTED_ACCESS = FULL, DIRECTORY_NAME = N'DemoFiletable' ) WITH NO_WAIT; |
|
1 2 3 4 5 6 7 8 9 10 11 12 13 14 15 16 17 18 |
--Used to hold the entire enventory of pictures CREATE TABLE [FileAssets].[Picture] AS FILETABLE ON [PRIMARY] FILESTREAM_ON [FilestreamData] WITH ( FILETABLE_DIRECTORY = N'Pictures', FILETABLE_COLLATE_FILENAME = Latin1_General_100_CI_AS, FILETABLE_PRIMARY_KEY_CONSTRAINT_NAME=[PK_Picture] ); --used to hold a set of pictures for viewing CREATE TABLE [FileAssets].[PicturePreview] AS FILETABLE ON [PRIMARY] FILESTREAM_ON [FilestreamData] WITH ( FILETABLE_DIRECTORY = N'PicturePreview', FILETABLE_COLLATE_FILENAME = Latin1_General_100_CI_AS, FILETABLE_PRIMARY_KEY_CONSTRAINT_NAME=[PK_PicturePreview] ); |
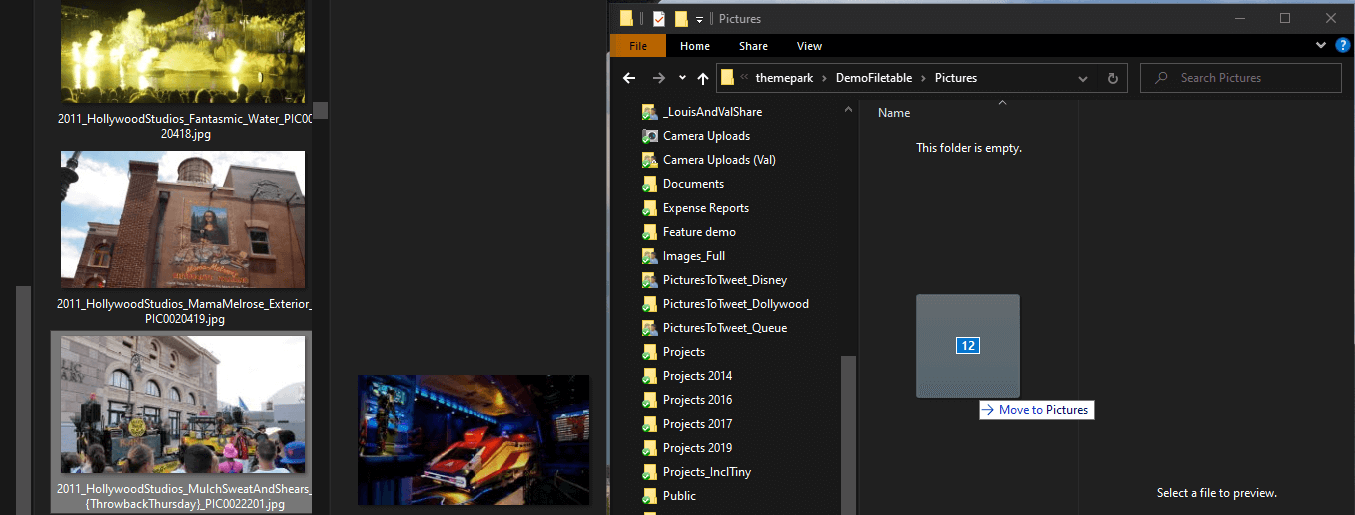 You may get a message about whether or not to copy the files without its properties. I was not using any of the properties from the image, so I said to allow it. Even after copying, the file had the details I typically care about, Date taken, dimensions, camera maker and model (helps me to know if I took the picture, or if it was mixed in and saved from online, but I post pictures I take, even if they aren’t always perfect!)
In Windows, the directory looks like any other Windows folder:
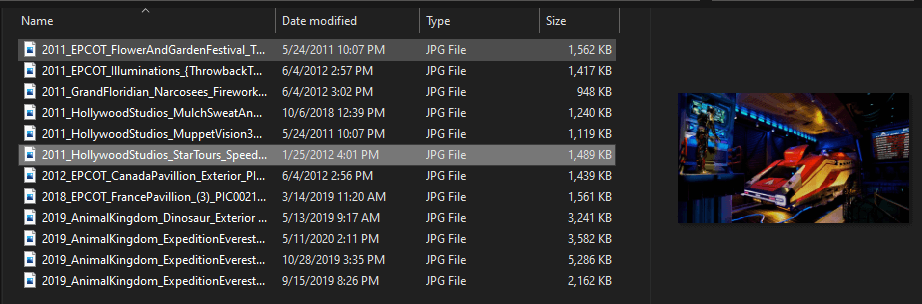 And in SQL, it looks like any other
table object with a large binary value, with the fixed structure of a filetable:
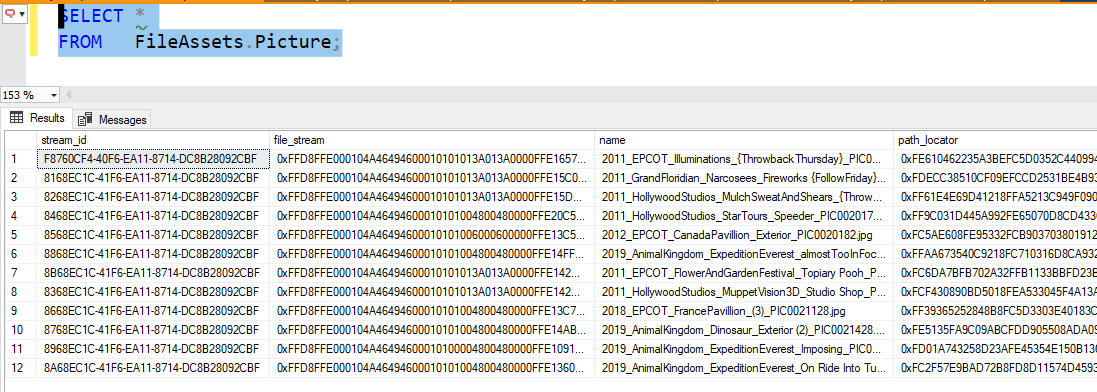 Even with just 12 files (and especially in my live “prod” db, with just over 2000 rows, it is noticeably slow to query the filetable object using
SELECT *, but if you don’t include the binary column (file_stream, which in my case is 1-5MB each), it is extremely fast.
To make sense out of the name column, I will build the following view object to query the metadata. It uses a function I built to mimic functionality in other RDBMSs that will pull a value out of a string called SPLIT_PART. I do this using a function I wrote Tools.String$SplitPart (which you can find here on Github along with the numbers table I use as part of the process). The interface is:
Tools.String$SplitPart(
@inputValue nvarchar(4000), --value being split
     @delimiter nchar(1) = ',', --the delimiter to split on
     @position int = 1) --position in the value to get
Using that object, this is the code of the view object:
|
1 2 3 4 5 6 7 8 9 10 |
CREATE VIEW [FileAssets].[PictureDecoded] AS SELECT Tools.String$SplitPart(name, '_',1) AS Year, Tools.String$SplitPart(name, '_',2) AS ThemeParkAreaHashtag, Tools.String$SplitPart(name, '_',3) AS ThemeParkAssetHashtag, Tools.String$SplitPart(name, '_',4) AS Tags, CAST(REPLACE(Tools.String$SplitPart(name, '_',5),'.jpg','') AS varchar(10)) AS PictureNumber, name AS PhysicalFileName FROM FileAssets.Picture WHERE name LIKE '%.jpg'; |
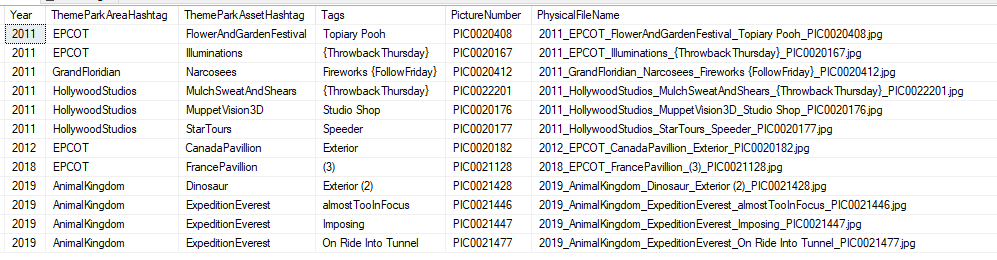 Using this metadata, I use it to load a database and use it to pick pictures. The database and a picture of the model, along with my most recent check-in from Red-Gate Source Control is here if you are interested. In the full version of the database, the tags are parse and normalized to their own table, naturally.
Just using this basic
view object, I created a stored procedure object to let me do some quick random searches.
|
1 2 3 4 5 6 7 8 9 10 11 12 13 14 15 16 17 18 19 20 21 22 23 24 25 26 27 28 29 30 31 |
CREATE PROCEDURE FileAssets.Picture$Search ( @TagLike varchar(50) = '%', @ThemeParkAreaHashTagLike varchar(50) = '%', @SamplePictureCount int = 2 ) AS --just clear the directory, so you can reload it TRUNCATE TABLE FileAssets.PicturePreview --insert into the preview directory, the binaries --that match INSERT INTO FileAssets.PicturePreview(stream_id, file_stream, name,path_locator, creation_time, last_write_time,last_access_time,is_directory, is_offline, is_hidden, is_readonly, is_archive, is_system, is_temporary) SELECT TOP (@SamplePictureCount) stream_id, file_stream, name,path_locator, creation_time, last_write_time,last_access_time,is_directory, is_offline, is_hidden, is_readonly, is_archive, is_system, is_temporary FROM FileAssets.PictureDecoded JOIN FileAssets.Picture ON Picture.name = PictureDecoded.PhysicalFileName --Picture name and path is an alternate key --and I am only using one dir in this part of --the process --a couple of like expression WHERE (ThemeParkAssetHashTag LIKE '%' + @TagLike + '%' --search for asset OR PictureDecoded.Tags LIKE '%' + @TagLike + '%') --or in the tags AND ThemeParkAreaHashTag LIKE @ThemeParkAreaHashTagLike --specify the location ORDER BY NEWID(); |
|
1 |
EXECUTE FileAssets.Picture$Search @SamplePictureCount = 5; |
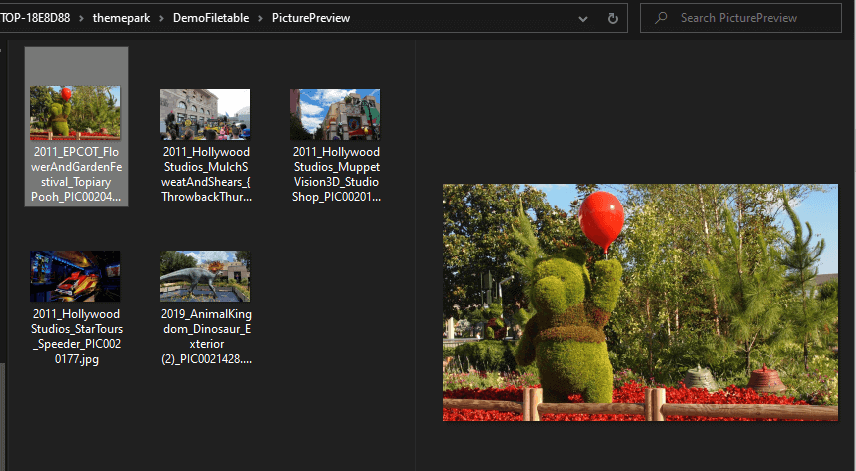 Execute it again, and you will see a different set of files. Nothing has changed in the
Pictures directory or FileAssets.Picture table, so you can do what you want with these files without concern for your source data. Or using the other parameters, you can get random pictures of something specific, like my favorite roller coaster:
|
1 2 3 4 |
EXECUTE FileAssets.Picture$Search @ThemeParkAreaHashTagLike = 'AnimalKingdom', @TagLike = 'ExpeditionEverest', @SamplePictureCount = 2; |
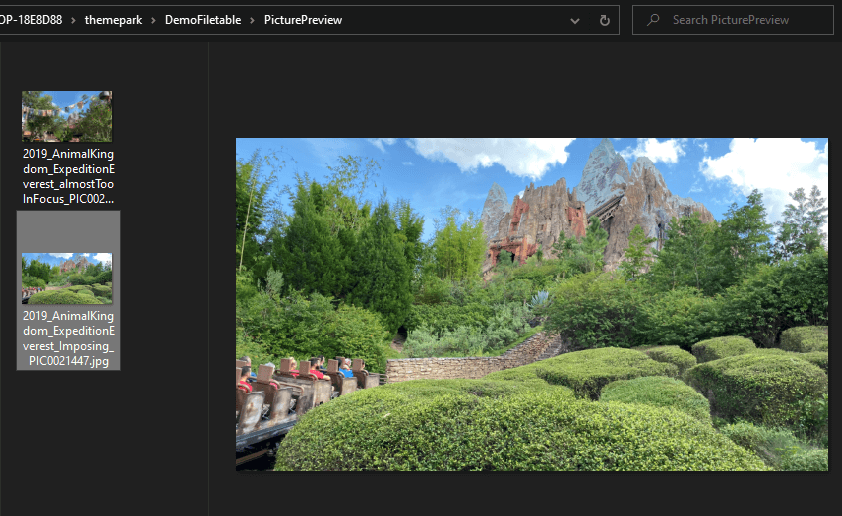 Now, my pictures are very manageable and searchable using SQL Server. The fact that the names are very standardized also helps me with searching the names in a file folder (I copy all of the files from the share into a Dropbox folder so I have access to the files everywhere I am as well.)
And additional cool thing is that even on my Express Edition local server, the filetable data is backed up with the database, so when I backup the database, it backs up my pictures in addition to the textual data. That extra backup, along with the copy of the files in Dropbox give me extra relief that I have a decent backup if something gets corrupted.
With just a little bit of configuration, and a little bit of code, I have a simple database of my images that I can search using T-SQL in a manner that is a lot more powerful that what I can reasonably do using File Explorer, along with the ability to keep history of how the pictures are used. This would be very useful for any photographer with a stock of pictures that they want to search and keep history of, even if it is just baby pictures…of the puppy.
FAQs
1. What is a SQL Server FileTable?
A FileTable is a specialised table type in SQL Server (introduced in 2012) where each row represents a file or directory in a Windows folder. The FileTable’s row columns include the file content (as VARBINARY(MAX) over FileStream), file metadata (name, path, size, dates, attributes), and system-managed hierarchy information (for nested folders). Files can be read and written both through T-SQL (INSERT, UPDATE, SELECT, DELETE) and through ordinary Windows file system APIs (drag-and-drop in Explorer, save-as from any application). This dual access is what distinguishes FileTables from storing file bytes in a regular VARBINARY column. FileTables require FileStream to be enabled on both the SQL Server instance and the containing database.
2. What is the difference between FileTable and FileStream in SQL Server?
FileStream is the underlying storage technology: it lets SQL Server store binary large objects (BLOBs) in the file system rather than inside the database file, with the database retaining transactional control over the files. FileStream columns behave like VARBINARY(MAX) for T-SQL access but store the actual bytes as files in a FileStream-enabled filegroup. FileTable is a higher-level feature built on FileStream that exposes a system-defined schema (file content, metadata, hierarchy) and additionally makes the files directly accessible via Windows file system APIs. In short: FileStream is for storing files managed only by SQL Server; FileTable is for storing files that users or external applications also need to touch through normal file operations.
3. How do I enable FileStream for a SQL Server FileTable?
Three levels of enablement: (1) Instance level – in SQL Server Configuration Manager, enable FileStream for the instance and choose the access mode (T-SQL access, or T-SQL plus file I/O access); (2) Server level – run EXEC sp_configure ‘filestream access level’, 2 followed by RECONFIGURE (level 2 enables both T-SQL and file I/O); (3) Database level – the database must have a FILESTREAM filegroup and a NON_TRANSACTED_ACCESS setting of FULL to support FileTables specifically. Once all three are set, you can CREATE TABLE … AS FileTable. The article walks through the specific T-SQL commands required.
4. When should I use a SQL Server FileTable instead of regular file storage?
Use a FileTable when you need both database-level querying of file metadata (SELECT by file size, date, name pattern) AND direct Windows file system access (users drag files into a folder, applications save directly, Explorer browsing works normally). Regular VARBINARY storage or FileStream-only storage works when only T-SQL access is needed. FileTables shine for document management systems, media asset libraries, email archives with user-accessible attachments, shared photo or image collections, and any application where you want transactional file management AND the convenience of ordinary file operations. They’re overkill for simple attachments on application records – a VARBINARY column or external blob storage is simpler there.
This document contains proprietary information and is protected by copyright law.
Copyright © 2026 Red Gate Software Limited. All rights reserved




Load comments